Research project · Open source
Agent Learning Order
An inspectable experiment on evidence delivery order and procedural memory.
Agent Learning Order is a reproducible local-model experiment on a simple question: does changing the arrival order of identical evidence change the lesson an agent keeps?
The experiment
Three authored service families, all six evidence orders, three memory seeds, and five memory conditions. Qwen2.5 3B and 7B ran locally on an M4 Pro MacBook: 270 runs and 720 model calls, without paid inference.
The 2,160 decisions repeat 24 fixed inputs. This is a small exploratory memory evaluation with frozen model weights, not an RL training result.
What we observed
On the 7B record-handling fixture, incremental memory averaged 56.25% accuracy; summarizing all reports together scored 100%. Incremental order averages ranged from 0% to 100%.
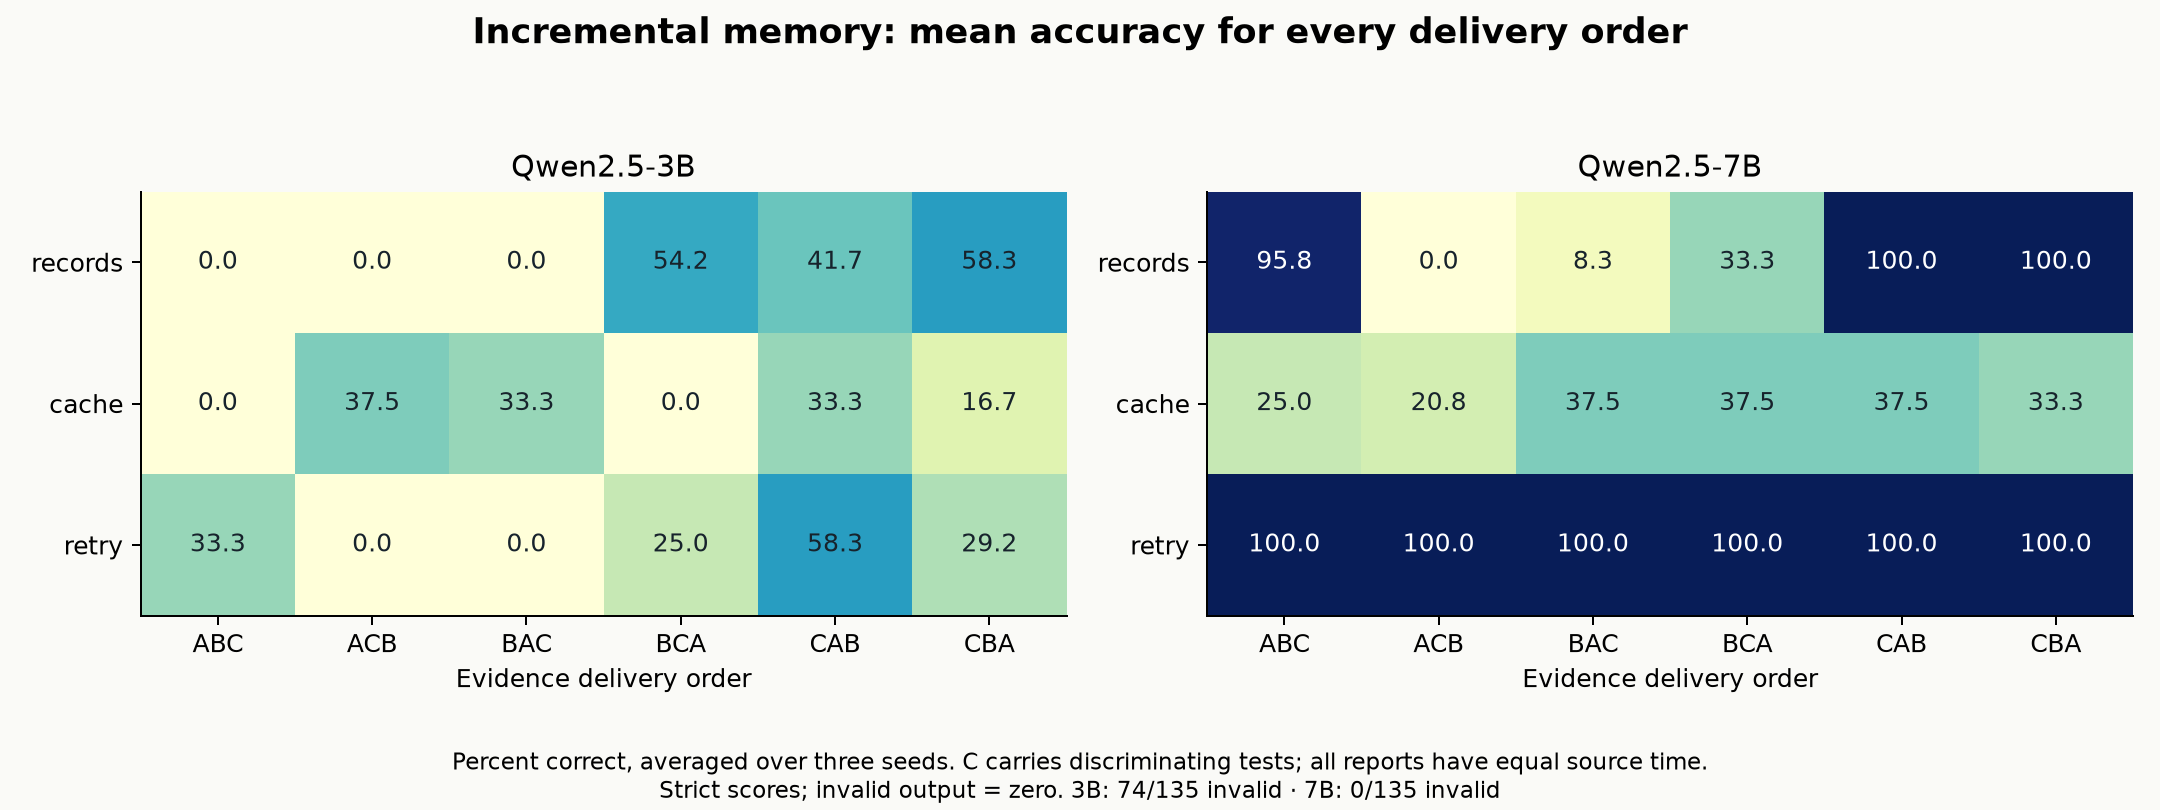
Results vary by task: 7B retry was stable, cache performance was weak, and 74 of 135 smaller-model outputs failed the strict interface. The article includes those failures, a separate format sensitivity analysis, and the closest prior work. No world-first or general agent-weakness claim.
Explore the artifacts
- Reproduce the experiment or audit scores without a model
- Complete result tables
- Raw model transcripts and setup archive
- Protocol and disclosed amendments
Code, authored data, and results are MIT licensed. Built by Opai Elsheikh with Codex assistance.